NVIDIA DGX Spark 4 TB Review: A Local AI Lab Not a Tiny Gaming PC
August 30, 2026
Workflow vs Autonomous Agent vs Multi-Agent System: Choose the Smallest Architecture
September 4, 2026
An agent does not gain useful memory merely because a conversation is long. Useful memory is selected, stored, retrieved and corrected outside the momentary model call. Without that lifecycle, more history can mean more noise, stale assumptions and privacy risk.
Separate four kinds of state
Working context contains what the model sees now. It is temporary and limited.
Session state preserves messages, tool results and task progress across turns in one piece of work.
Knowledge stores sourced facts, documents and structured records that may support many future tasks.
Experience memory preserves reusable lessons: a user preference, a correction, a project convention or a verified recovery procedure.
OpenAI’s sandbox documentation explicitly separates conversational session memory from sandbox memory that distils reusable lessons into files. This distinction prevents a full transcript from becoming the permanent knowledge model.
Design the write path before retrieval
Memory systems often start with search, but the hardest decisions occur when writing. Which observation deserves persistence? Is it a fact, a preference or a task-specific accident? Does it contain private information? What source supports it? When should it expire?
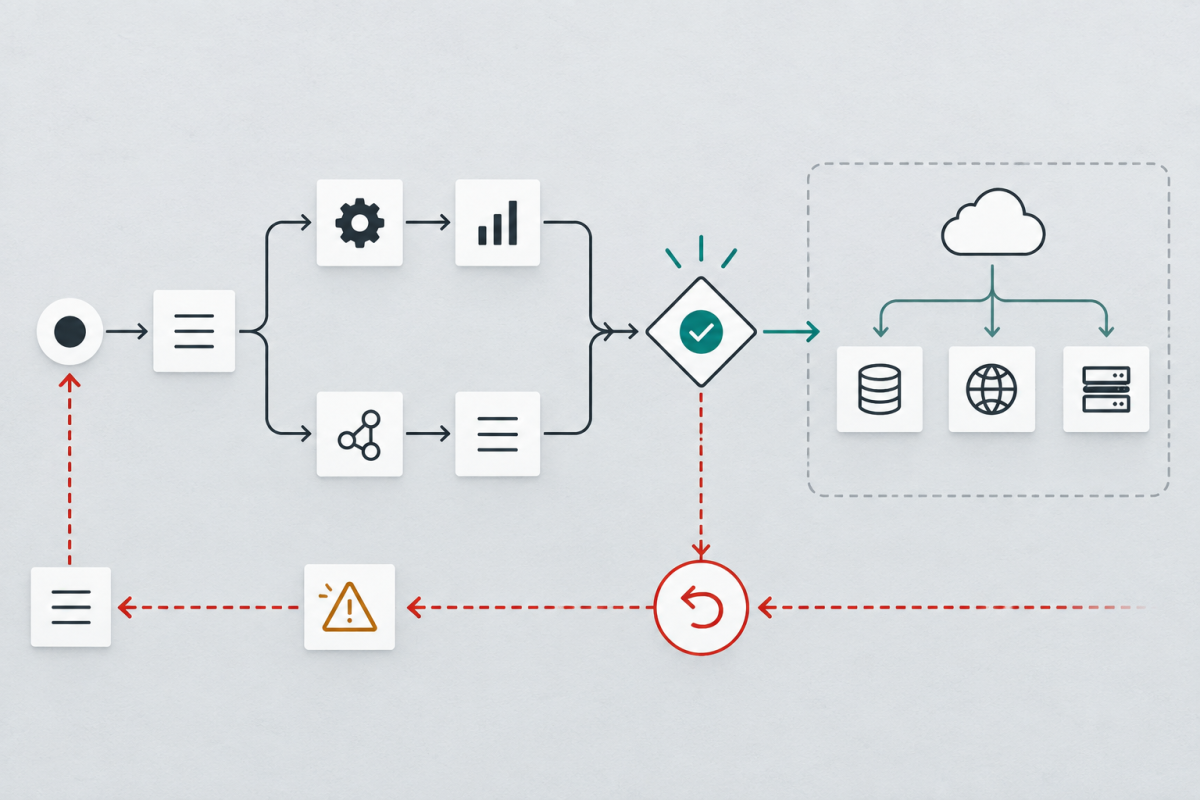
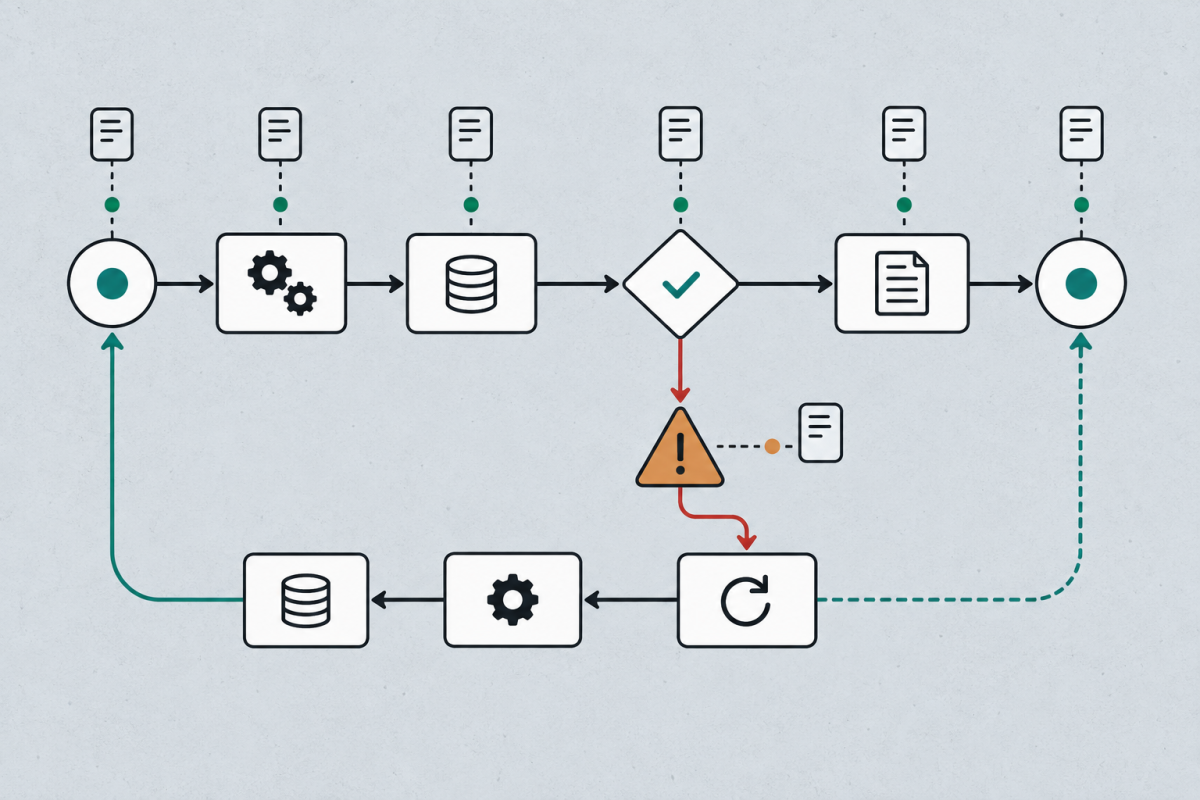
Use a structured record with source, date, confidence, context, privacy, status and authority. Store corrections as changes with provenance rather than silently replacing history. When two sources disagree, retain the conflict until stronger evidence or an authorized decision resolves it.
Retrieve progressively
Load a compact index first. Search details only when relevant. OpenAI documents a progressive memory layout in which a summary is loaded before deeper files and rollout histories. The exact implementation is product-specific, but the principle is portable: discovery metadata should be cheap; evidence should remain available on demand.
Retrieval must also respect privacy. A record that may be stored is not automatically safe for every agent, user or output. Apply access rules before content enters model context.
Consolidate offline
Do not let every successful or failed action immediately rewrite long-term instructions. Collect evidence during work, then review batches later. Merge duplicates, preserve applicability conditions, mark stale records and test proposed updates against both improvement cases and retention cases.
Memory can make an agent worse
Incorrect preferences become repeated errors. Old API advice can override current documentation. Large indexes can retrieve a plausible but irrelevant memory. Personal data may surface in a task where it does not belong.
Set capacity limits, freshness rules and deletion or archival procedures. Keep the raw source available when possible so a compressed memory can be audited.
When memory is unnecessary
A stateless task with complete input should remain stateless. Do not persist user information merely because the platform supports it. Memory is justified when future work benefits from an approved, reviewable lesson that cannot be supplied more safely at request time.
Continue with Build an AI Knowledge System With Provenance, Context Engineering and Continual Improvement.
Primary sources
- OpenAI: Sandbox agents and persistent memory
- OpenAI Agents API architecture
- A Survey on the Memory Mechanism of LLM-based Agents
Adaptation note: This article was informed by the memory and knowledge-base chapters of AI Agents in Depth: Design Principles and Engineering Practice by Bojie Li and contributors, Apache License 2.0. The structure, terminology and recommendations were independently rewritten and expanded for Stariy.com.