Apple Mac Studio M5 Ultra Review for Local AI: Memory Bandwidth Changes the Equation
September 24, 2026
AI Agent Safety: Permissions and Rollback
September 26, 2026
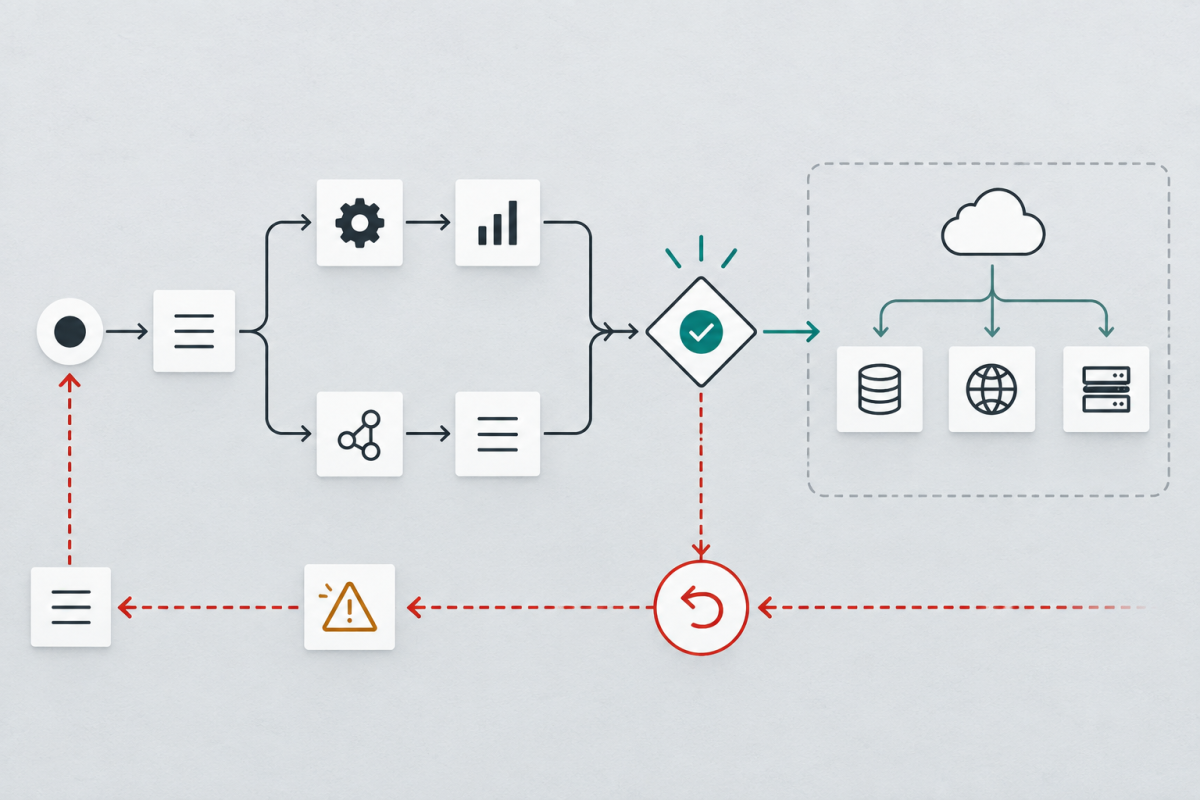
A prompt tells a model what to do at one moment. An agent needs something broader: a maintained working state that remains useful after tool calls, errors, discoveries and long stretches of work. That is the practical difference between prompt engineering and context engineering.
Anthropic describes context engineering as curating the information available to a model across system instructions, tools, external data and message history. The central constraint is not merely the maximum context-window size. It is relevance. A larger window can hold more noise, outdated observations and repeated tool output alongside the evidence that actually matters.
Start with a context contract
Before optimizing tokens, define what the agent needs to know at each decision point:
- the objective and completion condition;
- non-negotiable constraints;
- current state and completed work;
- approved tools and data boundaries;
- evidence needed for the next action;
- unresolved errors, risks and owner decisions.
This is different from placing the entire project history into one prompt. Context should be sufficient, not exhaustive.
Separate stable instructions from changing state
Stable rules belong in a predictable, versioned layer. Current progress belongs in a compact status record. Large source material belongs outside the prompt until retrieval is necessary. Tool results should return the smallest useful structure rather than a complete system dump.
This separation makes changes easier to understand. If behavior changes after a new rule, tool result or state update, the team can identify the responsible layer instead of comparing two opaque prompt blobs.
Retrieve just in time
Preloading every potentially useful document feels safe, but it forces the model to search through irrelevant material on every step. A better pattern is progressive disclosure: show a small catalog of available sources, then retrieve details when the task requires them.
Files, database identifiers and source links can remain as references until needed. The agent should preserve citations so that compressed notes can still be traced back to original evidence. Retrieval is not only about finding relevant text; it is about retaining enough provenance to review the decision later.
Compress without erasing decisions
Long tasks eventually need compaction. Good compaction keeps objectives, architectural choices, constraints, unresolved problems, failed approaches and source references. It removes redundant conversation, superseded observations and bulky outputs already stored elsewhere.
The worst summary is one that makes a failed path look as if it never happened. That lost failure may be exactly what prevents the next session from repeating the same mistake.
For research-heavy subtasks, isolation can be better than compression. A separate worker can explore a large corpus and return a bounded evidence package. The main agent remains focused, but the handoff must be self-contained because the worker does not share every hidden assumption.
Leave artifacts for the next session
Anthropic’s work on long-running agents emphasizes continuity through explicit artifacts. Treat an agent like an engineer handing a project to the next shift. Record what changed, what was tested, what remains broken and what should happen next. A repository, task ledger or structured status document is more durable than relying on the model to reconstruct state from a long conversation.
A practical review checklist
At each checkpoint, ask:
- Is the objective still visible and current?
- Which information is authoritative, and which is only an observation?
- Has any tool output become stale?
- Can bulky material move to storage and remain retrievable?
- Are decisions, failures and citations preserved?
- Could a fresh agent continue from the written artifacts?
Context engineering is not a technique for making prompts longer. It is the discipline of deciding what the agent may see now, what it can retrieve later and what must persist outside the model entirely.
Continue with Build an AI Knowledge System With Provenance for persistent knowledge, or How to Evaluate an AI Agent for regression testing.
Primary sources
- Anthropic: Effective context engineering for AI agents
- Anthropic: Effective harnesses for long-running agents
- Anthropic: Writing effective tools for agents
Source and adaptation note: This article draws on context-management concepts in AI Agents in Depth: Design Principles and Engineering Practice by Bojie Li and contributors, distributed under Apache License 2.0, and on the cited primary engineering sources. It was independently rewritten, reorganized and expanded for Stariy.com.